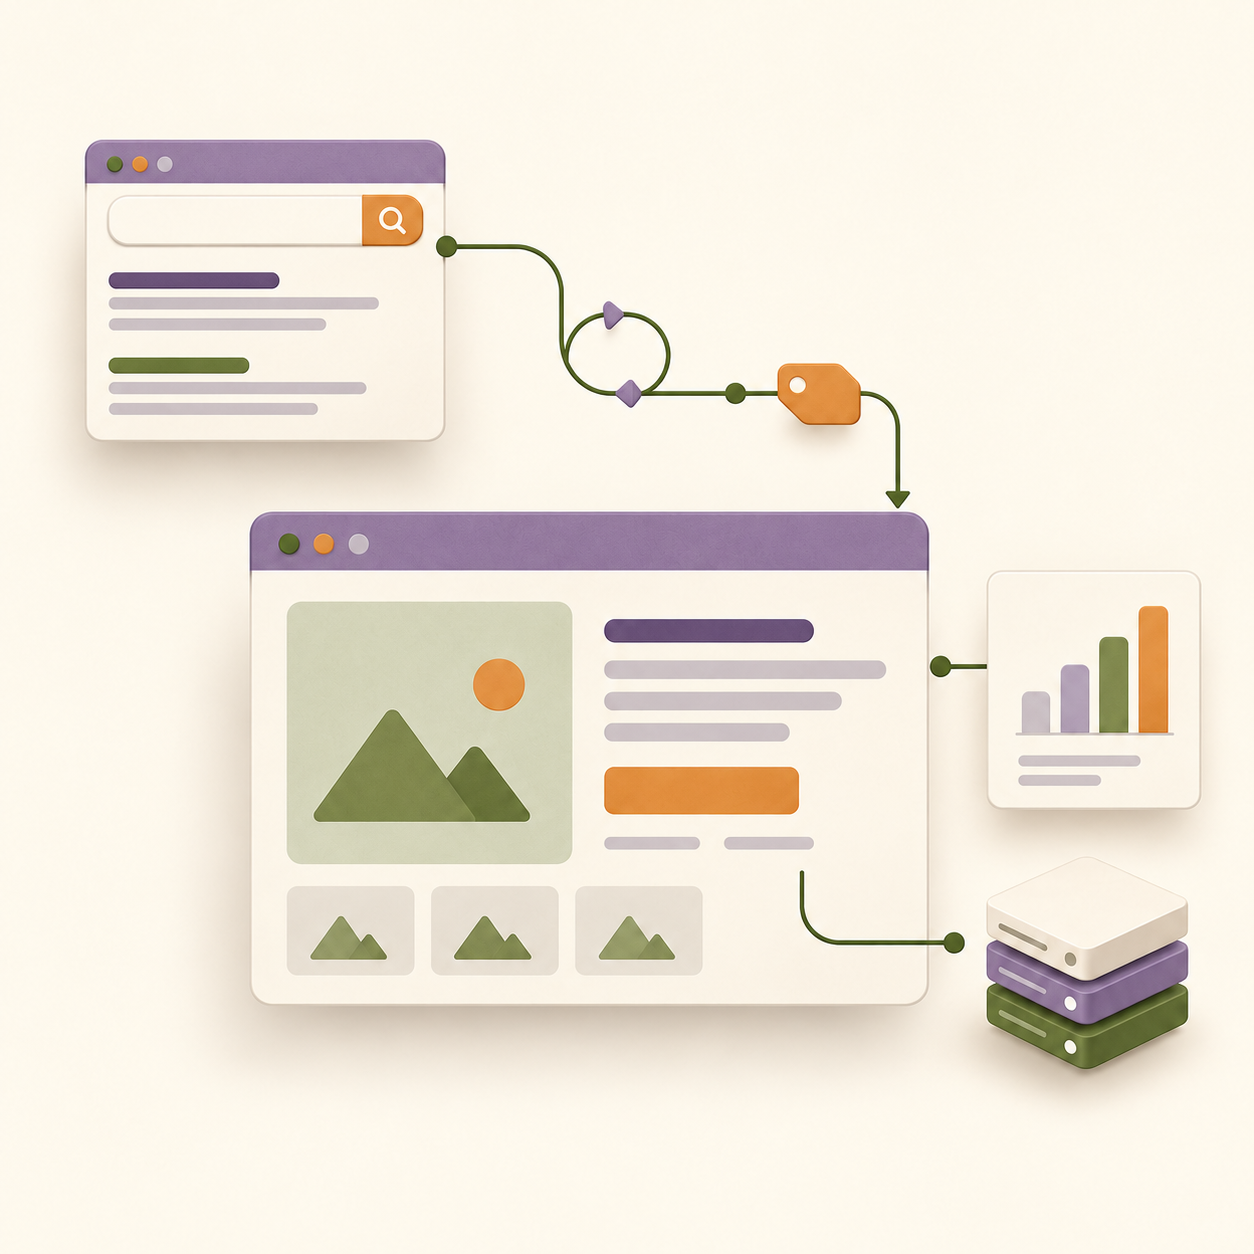
When a visitor clicks a Google result and lands on your website, the clicked link and the URL your server receives may contain more than the page address.
Two details can appear along that journey: a Google redirect through /goto and a landing-page parameter called srsltid. Each has a different role, which helps us understand what search tools need to read and what website analytics need to retain.
Older Google redirect links could include the destination directly inside a query parameter, such as /url?q=[target_url]. On results using the newer /goto format, the link instead contains an opaque token. The destination is no longer readable directly from that link. Tests of these redirects show Google returning an HTTP 302 response, with the destination supplied in the Location header.
A simplified request looks like this:
Separately, Google Merchant Center’s auto-tagging can add srsltid to a product landing URL. This parameter supports measurement of activity following clicks on free product listings, including purchases when key event tracking is configured.
The request reaching the store can then look like this:
Here’s the difference between two:-
- /goto is a redirect on Google’s domain. It routes the browser to the destination website.
- srsltid is a parameter on the destination URL. Merchant Center adds it through auto-tagging to support attribution.
A /goto redirect does not, by itself, mean the destination will contain srsltid.
If you’re someone managing search performance, the work continues after a result earns a click. Search tools need to identify the correct destination, redirects need to preserve required tracking information, and reporting needs to keep visits to the same page together.
This article follows that journey from the Google result to the website and its analytics, with request examples, configuration snippets, and workflows for checking how each stage behaves.
How Google’s /goto redirects change search result links
Google’s /goto format changes how we read a search result’s destination. On affected results, the link points to a Google redirect containing an opaque token. A tool that simply copies the link’s href may therefore save the Google URL instead of the page appearing in search.
How older Google links exposed the destination
Earlier link formats commonly made the destination available in one of two places.
A direct link with a separate click notification
The anchor’s href contained the website URL, while its ping attribute supplied an endpoint for reporting the click:
When hyperlink auditing is supported and enabled, the browser sends an HTTP POST to the ping endpoint while navigating to the address in href. These are separate requests, and browsers can suppress the notification according to user preferences.
For a URL extraction tool, the destination was easy to read directly from the anchor.
A redirect with the destination inside a query parameter
Another format routed navigation through Google’s /url endpoint:
Here, the destination remained available in the url parameter. Percent-decoding https%3A%2F%2Fwww.example.com%2Fpage produced https://www.example.com/page.
Both formats allowed a parser to recover the destination from the link itself.
What the /goto token tells us
A /goto link has a different structure:
The value after url= does not expose the destination as a readable or percent-encoded address.
Published tests have decoded the outer structure of sampled tokens as Protocol Buffers, a format for storing structured binary data. That does not establish the meaning of every field, the encryption method, or which Google systems process it. The same tests found no readable destination inside the sampled payload.
We should therefore treat the token as an opaque value to resolve. Its appearance alone does not tell us whether it contains a ranking position, timestamp, session identifier, or replay-prevention value.
How the redirect is resolved
The observable workflow is straightforward:
- The browser or URL resolver sends a GET request to Google’s /goto endpoint.
- For a valid token, Google returns an HTTP 302 response containing the destination in its Location header.
- The browser follows that destination to load the website.
- A URL extraction tool can instead record the Location value without downloading the destination page.
A simplified request and response look like this:
The request method matters. In published tests, GET returned the redirect, while HEAD returned 200 without a Location header. A resolver should check the actual response rather than assume both methods behave alike.
What changes for search and AI tools
A basic parser might start with a selector such as document.querySelectorAll('div#rso a') and inspect the collected anchors.
When those anchors contain /goto links, collecting their href values is only the first step. The parser still needs to identify the destination associated with each result.
A redirect-based workflow would:
- Retrieve the search results page.
- Collect and deduplicate the relevant /goto links.
- Request each unresolved link and read its Location header.
- Store the destination URL alongside the result’s title, position, and other data.
For a hypothetical page containing 100 distinct redirect links, resolving every link this way would require one page request plus 100 resolution requests. The added cost depends on connection reuse, concurrency, response size, and request limits.
However, following every redirect is not always necessary. Tests have also found destination URLs in embedded page data, allowing parsers to pair some tokens with their destinations without extra requests.
The same extraction issue can affect retrieval-augmented generation, or RAG, workflows that use Google results to find source pages. An unresolved redirect can delay retrieval or leave the system storing a Google URL as its source. These are possible effects on the workflow; they do not establish Google’s intent behind the change.
What changes for click measurement
A direct link with a ping attribute separates navigation from the click notification. The visitor can reach the website even when the browser suppresses that notification.
With /goto, successful navigation through the supplied link first requires a request to Google. From this request flow, we can infer that Google has a server-side opportunity to record the interaction.
That opportunity does not guarantee complete conversion attribution. Measuring what happens after arrival still depends on the destination website, its tracking setup, consent settings, and browser behavior.
Here’s how the link formats compare:-
For search reporting, the practical check is whether the tool records the actual destination page. Once that URL is resolved, we can examine any parameters added to the landing URL, including srsltid.
How srsltid connects product visits to purchase reporting
Once a visitor reaches a product page, the website needs to measure what happens next. A click tells us someone arrived. Purchase tracking helps us assess whether that visit led to a sale.
Google Merchant Center uses srsltid as part of this measurement process. With auto-tagging enabled, Google can append the parameter to URLs for free product listings. It supports attribution when the merchant has also configured a key event source and purchase tracking.
This gives /goto and srsltid separate roles in the same journey. The redirect routes navigation through Google. The result ID travels to the destination as part of the landing URL.
How srsltid differs from UTM parameters
UTM parameters describe a traffic source using readable labels:
In this example, the labels identify Google as the source, organic as the medium, and free_shopping as the campaign. Everyone following the same tagged link can receive those same values.
Analytics can use these labels to group visits and report their outcomes. The labels themselves do not identify an individual listing interaction.
An srsltid value looks different:
It is an opaque result ID rather than a description we can read. For implementation, we need to preserve it through the relevant landing-page journey so tracking can use it.
There is also a detail that matters when interpreting these values. Google says the result ID is created at the time of an impression. If a customer clicks the same free listing again, the same ID can be reused. We therefore cannot assume that every click produces a new value or count distinct IDs as an exact count of clicks.
The string alone also does not establish its internal contents. We should avoid treating it as a readable record of the merchant account, product SKU, ranking position, or timestamp.
How Merchant Center adds the parameter
Auto-tagging controls whether Merchant Center adds srsltid to eligible product links.
The workflow starts with the product URL supplied to Merchant Center:
From there:
- The merchant submits the product and its landing URL. Product data can be supplied through a feed, an API, or another supported method.
- Google displays the eligible product listing. The listing gives the shopper a route to the supplied landing page.
- Auto-tagging determines whether the landing URL receives srsltid. When enabled, the URL can include the result ID. When disabled, this feature does not add it.
- The shopper reaches the website. The site’s redirects and tracking setup determine whether the parameter remains available for measurement.
The resulting URLs can look like this:
Other parameters already present in the supplied URL can remain in either case. Turning off auto-tagging controls this tagging feature; it does not remove unrelated parameters.
Auto-tagging is only one part of purchase measurement. Merchant Center also needs a key event source, such as a linked GA4 property or a Google tag configured to send purchase details. A tagged visit alone does not create a purchase record.
Where srsltid fits among Google’s tracking parameters
Google uses different parameters for different traffic and measurement systems. Their presence helps identify which setup we need to check.
Google’s documentation describes the advertising roles of gclid and dclid, and distinguishes gbraid for web-to-app measurement from wbraid for app-to-web measurement.
For a merchant, srsltid helps connect free product discovery with business results. The next step is to trace the complete request sequence and check whether the website carries that information through to its tracking system.
What happens from the Google click to the analytics event
To check whether a search visit is measured correctly, we need to follow it through four stages: the request to Google, the redirect response, the website request, and the analytics event.
Each stage passes information to the next. Tracing that handoff helps us locate a missing parameter, an unexpected redirect, or a tracking event that never fires.
The workflow below illustrates a product visit using both /goto and Merchant Center auto-tagging. The request examples use simplified HTTP-style notation. Tokens are illustrative, and actual response headers can vary.
Here's the complete request sequence
This sequence shows the visible handoff. It does not require us to assume how Google decrypts a token or which internal systems process it.
Step 1 The browser requests the Google redirect
When the visitor clicks a result using /goto, the browser requests the Google URL:
At this point, the browser is requesting a navigation through Google. The store has not yet received the product-page request.
For a valid token, published tests show Google returning the destination in a 302 response.
Merchant Center auto-tagging can supply srsltid on eligible product landing URLs. The result ID may already have been created at the impression stage, so this workflow does not assume that Google generates it when the redirect request arrives.
Step 2 Google returns the destination
An illustrative redirect response looks like this:
Two headers explain the next step.
Location supplies the address to request. In this example, it contains the product URL and its srsltid parameter.
Referrer-Policy controls the referrer information sent onward. Under origin-when-cross-origin, navigation from Google to another origin sends the Google origin, such as https://www.google.com/, while omitting the search page’s path and query string.
The cache directives shown apply to this illustrative redirect response. The store applies its own caching rules when the browser requests the product page.
Step 3 The browser requests the product page
The browser opens or reuses a secure connection to the store and follows the supplied address:
The store now receives two separate pieces of information:
- The query string contains srsltid. It is part of the requested URL.
- The Referer header identifies the referring origin. Its presence and value depend on the applicable policy and browser behavior.
The website may return the page immediately or perform another redirect, such as moving to a preferred hostname or adding a trailing slash. We need to inspect that additional response to see whether it preserves the parameter.
Caching also depends on configuration. If a cache key includes srsltid, different values can produce separate cache entries for the same product page. A cache can instead exclude that parameter from its key where appropriate.
After any redirects, a successful page request returns the HTML with a 200 response.
Step 4 The website sends its analytics event
As the page loads, permitted tracking tags run. The Google tag may be installed directly or deployed through Google Tag Manager.
The measurement workflow is:
- Read the landing-page information. The current URL includes any parameters that survived the redirect chain. JavaScript can access its query string through window.location.search.
- Read the available referrer. The page exposes this through document.referrer.
- Send the configured event. A GA4 measurement request, such as one to /g/collect, can carry page and session information.
- Process the measurement data. Attribution depends on the information received and the configured connections between the website, analytics, and Merchant Center.
Google documents page_location as defaulting to the document’s URL and page_referrer as defaulting to document.referrer. Custom tag settings can override those values.
Purchase reporting requires the later purchase event and a configured Merchant Center key event source. A successful landing-page event alone does not establish that a purchase was recorded.
Where to check when the handoff fails:-
The useful diagnostic is the first point where the expected information changes. Comparing the redirect destination, final landing URL, and analytics request lets us assign the fix to the right part of the system.
How tracking parameters affect indexing and page experience
A tracking parameter can leave a product page unchanged while changing how its URL is cached, shared, and reported.
For srsltid, we need to check three things: whether the page points to a consistent canonical URL, whether caching treats the parameter as a content difference, and whether shared links retain unnecessary tracking values.
These checks help us identify actual website issues without treating every tagged URL as an indexing problem.
Keep the canonical URL consistent
When srsltid does not change the page’s content, the tagged and untagged versions should point to the same preferred URL.
For example:
On the clean product URL, this is a self-referencing canonical. On a tagged version, the same element points back to the clean product URL.
The problem starts when a template builds the canonical from the complete incoming request, including its tracking parameters:
This gives different tracking variants different declared canonical URLs, even though they serve the same product.
Generate the canonical from the page’s preferred address, with consistent hostname and path rules. Keep internal links and sitemap entries aligned with that address. Google treats canonical annotations as a strong signal and considers other signals when choosing the indexed version.
In Search Console, inspect representative tagged URLs and compare the user-declared canonical with the Google-selected canonical. An “Alternate page with proper canonical tag” status can be an expected outcome for a duplicate URL. The useful question is whether Google selected the intended product page.
Check how tagged URLs enter the crawl queue
Tagged URLs can also spread through links that visitors copy and share.
A typical discovery path is:
- A shopper clicks a product listing and reaches a URL containing srsltid.
- The shopper copies that URL from the address bar.
- They paste it into a public forum, blog, or another crawlable page.
- A crawler discovers the tagged address.
- If it fetches the address, the website returns the page and its canonical information.
The discovered link might look like this:
Discovery does not guarantee that Googlebot will fetch every variant. However, large numbers of duplicate URLs can consume crawling resources when they are requested repeatedly.
Google’s crawl-budget guidance focuses on large or rapidly changing websites. For those sites, check server logs for repeated requests to parameter variants and compare them with crawling of new or updated pages. The parameter’s presence alone does not prove that product discovery is being delayed.
Check whether srsltid splits the cache
A cache key tells the CDN which stored response matches an incoming request.
When the key includes the complete query string, its URL component can be represented as:
Other headers or settings may also contribute to the full key.
Cloudflare’s default cache key includes the query string. CloudFront lets teams configure which query parameters affect caching. The behavior therefore depends on the platform and its settings.
The following example illustrates a possible difference. Its timings are hypothetical:
Different result IDs can create separate cache entries for identical content. That can reduce cache reuse, increase origin requests, and slow the initial response.
Where the parameter does not affect the response, exclude srsltid from the cache key while keeping it available for tracking. Preserve parameters that change the actual content, such as language or product options. AWS recommends caching based on parameters that produce different responses.
Also verify that the page is eligible for caching. A page configured to bypass the cache will not gain cache hits from changing its key alone.
Make shared links easy to reuse
Long tracking values make copied links harder to read and introduce extra URL variants into messages, social posts, and published links.
Use the preferred product URL in sharing buttons, internal links, and editorial references. Test whether tagged links still open correctly and produce the expected preview on the platforms your customers use.
Google can consolidate link signals across duplicate URLs when it selects a common canonical. A backlink containing srsltid does not automatically lose its value. Consistent linking helps keep the preferred address clear.
If the website removes srsltid from the address bar, time that change around the tracking setup. We need the attribution information available when the relevant tag reads the landing URL.
Together, these checks keep the product address consistent while allowing the visit to be measured. The next section examines how that information appears in GA4 and where attribution can break.
How srsltid affects GA4 attribution and reporting
When Merchant Center and GA4 show different results, we need to check what each system received and how the report groups that information.
Three checks help locate the problem: whether the visit retains its traffic-source information, whether GA4 assigns the expected channel, and whether tracking parameters split one product page into multiple reporting rows.
Why a redirect can retain Google’s referrer
A /goto redirect does not automatically remove the referring source.
For example, a redirect response can specify:
Under this policy, navigation to another origin sends the referring origin while omitting its path and query string. The request reaching the store can therefore contain:
The browser applies the relevant referrer policy across the navigation. Privacy settings and other controls can also affect what reaches the destination. HTTPS alone does not guarantee that the referrer will be present.
On the landing page, GA4’s page_referrer defaults to document.referrer. Together with campaign information and platform integrations, this helps determine the traffic source.
How GA4 separates search and shopping traffic
GA4 uses channel definitions based on the traffic-source information available to it.
For manually classified traffic, the Organic Search definition can be summarized as:
For Merchant Center traffic, Google documents this Organic Shopping rule:
Manual traffic can also qualify for Organic Shopping through a listed shopping source or a campaign name matching Google’s shopping pattern. The published definitions do not express this as a simple check for srsltid in the URL.
When checking acquisition, compare Session default channel group, Session source / medium, and Session source platform. Keep the scope consistent: a first-user acquisition dimension and a session acquisition dimension describe different points in the visitor’s history.
Check whether website redirects drop the parameter
Website redirects may change the hostname, letter casing, or trailing slash before the product page loads.
A rule that discards the query string can produce this sequence:
The final URL no longer contains srsltid. That removes the result ID from the address available to the landing-page tag.
Losing srsltid does not automatically make the visit Direct. Google’s referrer or other source information may still be available. Direct attribution becomes a concern when GA4 lacks usable information about the visit’s origin. Google lists missing tracking information and redirects among the causes to investigate.
Follow the complete redirect chain and inspect both the final URL and the referrer sent with the analytics event.
Check whether browser controls change the landing information
A browser or extension can remove tracking parameters before the website’s tag reads them. Brave’s release notes, for example, document removal of srsltid from URLs.
Test the journey across the browsers your customers use, checking:
- Whether srsltid remains in the landing URL when tracking runs.
- Whether document.referrer still contains Google’s origin.
- Whether the analytics request is sent.
- Whether custom tag settings replace the collected URL or referrer.
Parameter removal and tag blocking have different effects. A removed parameter changes the information available for attribution. A blocked tag can leave the visit absent from analytics altogether.
These differences can contribute to gaps between Merchant Center activity and GA4 reporting.
Use the right page dimension to avoid fragmented reports
Dimensions that include query strings can treat these addresses as separate values:
GA4 distinguishes between:
Google’s reporting documentation defines these fields separately. A report using a path-only dimension will not split rows solely because srsltid differs.
Large numbers of distinct URL values increase cardinality, meaning the number of unique values in a dimension. This can make reports more likely to reach row limits and aggregate remaining values into (other).
In BigQuery, grouping by the raw page_location can also separate tracking variants. Use a normalized page field for content-performance reporting, retaining parameters that change the page’s meaning.
For a reliable check, follow one tagged visit from its landing URL to its analytics request, then examine its source and channel dimensions after processing. That shows whether the fix belongs in redirects, tag configuration, platform connections, or the report itself.
How to Fix tracking and URL handling without losing attribution
A tracking parameter can affect several parts of a website. Redirects control whether it reaches the landing page. Analytics tags read it for attribution. Cache rules determine whether it creates another cached version of the same content.
At Centauri, we start with the layer causing the problem. The fixes below address different parts of that workflow, so apply each where it serves a clear purpose.
Clean the address bar after tracking reads the landing URL
The History API lets you remove srsltid from the address bar without reloading the page. replaceState() updates the current history entry, keeping the visitor on the same page.
Timing matters. The browser’s load event does not establish that every analytics tag has processed the original URL. Consent settings and asynchronous tag loading can delay that step.
Use a function that your tracking workflow calls after the relevant tags have read the landing URL.
The workflow is:
- Let the relevant tracking tags read the original landing URL, following the visitor’s consent choice.
- Call cleanTrackingUrl() at the verified completion point in that workflow.
- Check that the cleanup keeps filtering, navigation, and purchase tracking working.
- Confirm that history-change tracking does not record an extra page view.
This example removes only srsltid. Review other parameters separately before adding them to the cleanup function.
Preserve parameters through website redirects
A visitor may pass through HTTP-to-HTTPS, hostname, or trailing-slash redirects before reaching a product page. Each redirect needs to retain the query string.
For example:
http://store.com/products/widget?srsltid=example
should reach the website’s preferred URL with the parameter still present:
https://www.store.com/products/widget/?srsltid=example
Nginx
In Nginx, $request_uri contains the original request URI, including its query string. $uri contains the normalized path. Using $uri alone in a redirect drops the arguments.
These are configuration fragments. Add them to the existing server setup, including its TLS certificate directives.
For routes that require a trailing slash, retain the arguments explicitly. Place this fragment inside the existing www.store.com HTTPS server block.
Adjust the route pattern to match the website’s URL policy. A rule covering every extensionless path can also affect API endpoints and other routes.
Apache
Apache preserves the original query string when a redirect destination has no query string of its own. The QSA flag combines query strings when the destination introduces new arguments; it is optional in these examples.
If TLS terminates at a reverse proxy, use the deployment’s trusted scheme detection to prevent redirect loops.
Test the full redirect chain with srsltid and a functional parameter, such as a product variant or filter. Both should arrive at the final URL.
Exclude tracking values from cache keys
When srsltid does not change page content, including its value in the cache key can create multiple cached entries for the same page.
Apply exclusions to pages already safe to serve from a shared cache. Keep parameters that change the response, including language, product variants, filters, and pagination.
Cloudflare
Where the account plan supports selective query-string exclusions:
- Open Caching → Cache Rules.
- Create or edit a rule for the relevant product pages.
- Open the custom cache key settings.
- Set the query-string configuration to exclude srsltid.
- Retain parameters that affect page content.
Selective exclusions depend on the Cloudflare plan. This setting changes the cache key while retaining the parameter in the request unless another rule rewrites it.
Check that shared HTML does not contain visitor-specific tracking values before allowing tagged requests to share a cached response.
Fastly or Varnish
For a VCL setup, first decide whether the origin needs srsltid. If it does, configure the cache key separately from the forwarded request.
The following example is a request rewrite. It removes srsltid from req.url, so the origin receives the cleaned URL. The browser’s address bar retains the original URL.
Merge this logic into the existing vcl_recv function.
The cleanup handles the parameter at the beginning, middle, or end of the query string, including repeated occurrences. Other parameters remain.
Use this approach when the origin can serve the page without the tracking value. Validate the VCL against the platform’s configuration tools before deployment.
CloudFront
CloudFront can exclude a parameter through its cache policy. Under the query-string settings, choose Include all query strings except and specify srsltid. Review the other included parameters against the page’s content requirements.
If the origin needs the parameter, use an origin request policy to forward it separately. CloudFront supports forwarding query parameters that are absent from the cache key.
A CloudFront Function offers a request-rewrite alternative:
Attach it to the Viewer Request event for the relevant cache behavior. The function changes the request CloudFront processes and forwards. The visitor’s displayed URL keeps the parameter, while the origin receives the cleaned request.
Choose between cache-policy exclusion and request rewriting according to where attribution is handled. Measure cache reuse and response times after the change.
Review Merchant Center auto-tagging before switching it off
Merchant Center auto-tagging supports purchase attribution when a key-event source and purchase tracking are configured. Enabling the toggle alone does not complete that setup.
If there is a measured reason to disable it, the current settings path is:
Settings → General → Key event setup → Auto-tagging
Turn the setting off, then check new visits from Merchant Center listings and the reporting affected by the change.
For GA4, verify the recorded source platform and channel. Google’s published Merchant Center rule assigns Organic Shopping when the source platform is Shopping Free Listings. Removing srsltid does not guarantee a move to Organic Search.
Before publishing changes, test tagged and untagged product visits through the full journey. Confirm that redirects retain required parameters, analytics reads the intended landing URL, purchase events still arrive, and cached pages return the correct content. That check connects cleaner URLs to reliable reporting and a working customer journey.
Verify the full journey from search click to purchase
Google’s /goto redirects and Merchant Center’s srsltid tagging affect different stages of a visit. Your website needs to handle the incoming request, serve the right page, and retain the information required for reporting.
The practical task is to keep those stages aligned. A URL cleanup can affect tracking timing. A cache change can affect the request reaching the origin. A redirect can preserve the preferred page address while dropping useful parameters.
Use the checklist below to verify the complete workflow with your SEO, analytics, and development teams.
Check canonical URLs and indexing signals
Canonical tags, internal links, and sitemaps should consistently identify the preferred page URL. Google treats canonical annotations as signals and makes its own canonical selection
Check redirects and incoming requests
Check CDN cache behavior
Check browser cleanup and analytics timing
Check GA4 attribution and reporting
Check Merchant Center settings and ownership
At Centauri, we approach indexing readiness through clear content and consistent technical signals. For an e-commerce website, that work also needs reliable measurement of the visits and purchases that follow discovery.
Keep the preferred URL consistent, preserve tracking information where it is needed, and verify changes through a complete visitor journey. This gives your team evidence to act on when indexing, reporting, or performance changes.
Frequently asked questions
What is the srsltid parameter in Google URLs?
srsltid is a result ID added through Google Merchant Center auto-tagging. It helps connect visits from free product listings with purchases when tracking is configured. Auto-tagging is one part of that setup; Merchant Center also needs a key-event source and purchase tracking.
What does a Google /goto URL do?
A /goto URL is an intermediate Google URL that redirects a visitor to the destination website. It has been observed in some search results. The redirect and srsltid serve separate functions, so a /goto link does not necessarily produce a tagged landing URL.
Does every Google click get a new srsltid value?
No. Google states that the result ID is created when a listing receives an impression. If a customer clicks the same listing again, the same ID can be reused. Treating each srsltid value as a unique visitor or individual click can therefore produce misleading counts.
Does srsltid cause duplicate content or indexing problems?
Its presence alone does not prove an indexing problem. A tagged URL can serve the same content as the preferred page URL.
For those matching pages, keep canonical tags, internal links, and sitemap entries consistent. Then inspect Google’s selected canonical in Search Console. Canonical signals help Google consolidate duplicate URLs, although Google makes the final selection.
Does srsltid automatically classify a GA4 visit as Organic Shopping?
Google’s published rule for Merchant Center traffic assigns Organic Shopping when the source platform is Shopping Free Listings. The rule is not simply a check for srsltid in the URL. Inspect the recorded source platform and channel when validating attribution.
Can we remove srsltid from the browser’s address bar?
Yes. window.history.replaceState() can update the displayed URL without reloading the page.
Schedule that cleanup after the relevant tracking tags have read the original landing URL. Test it with consent settings, delayed tag loading, and application routing. Preserve other parameters that control product selections, filters, or navigation.
Can srsltid reduce CDN cache reuse?
It can when the CDN includes the parameter in its cache key. Different values may create separate cache entries for identical content.
Where the page is safe to share from cache, exclude tracking-only parameters while retaining those that change the response. Cloudflare supports selective query-string exclusions on eligible plans.
Should we disable Merchant Center auto-tagging?
Review your purchase-attribution needs before disabling it. Google identifies auto-tagging as a required part of Merchant Center key-event tracking, alongside the remaining tracking setup.
You can change it under Settings → General → Key event setup → Auto-tagging. Test the effect on reporting before making the change permanent.